
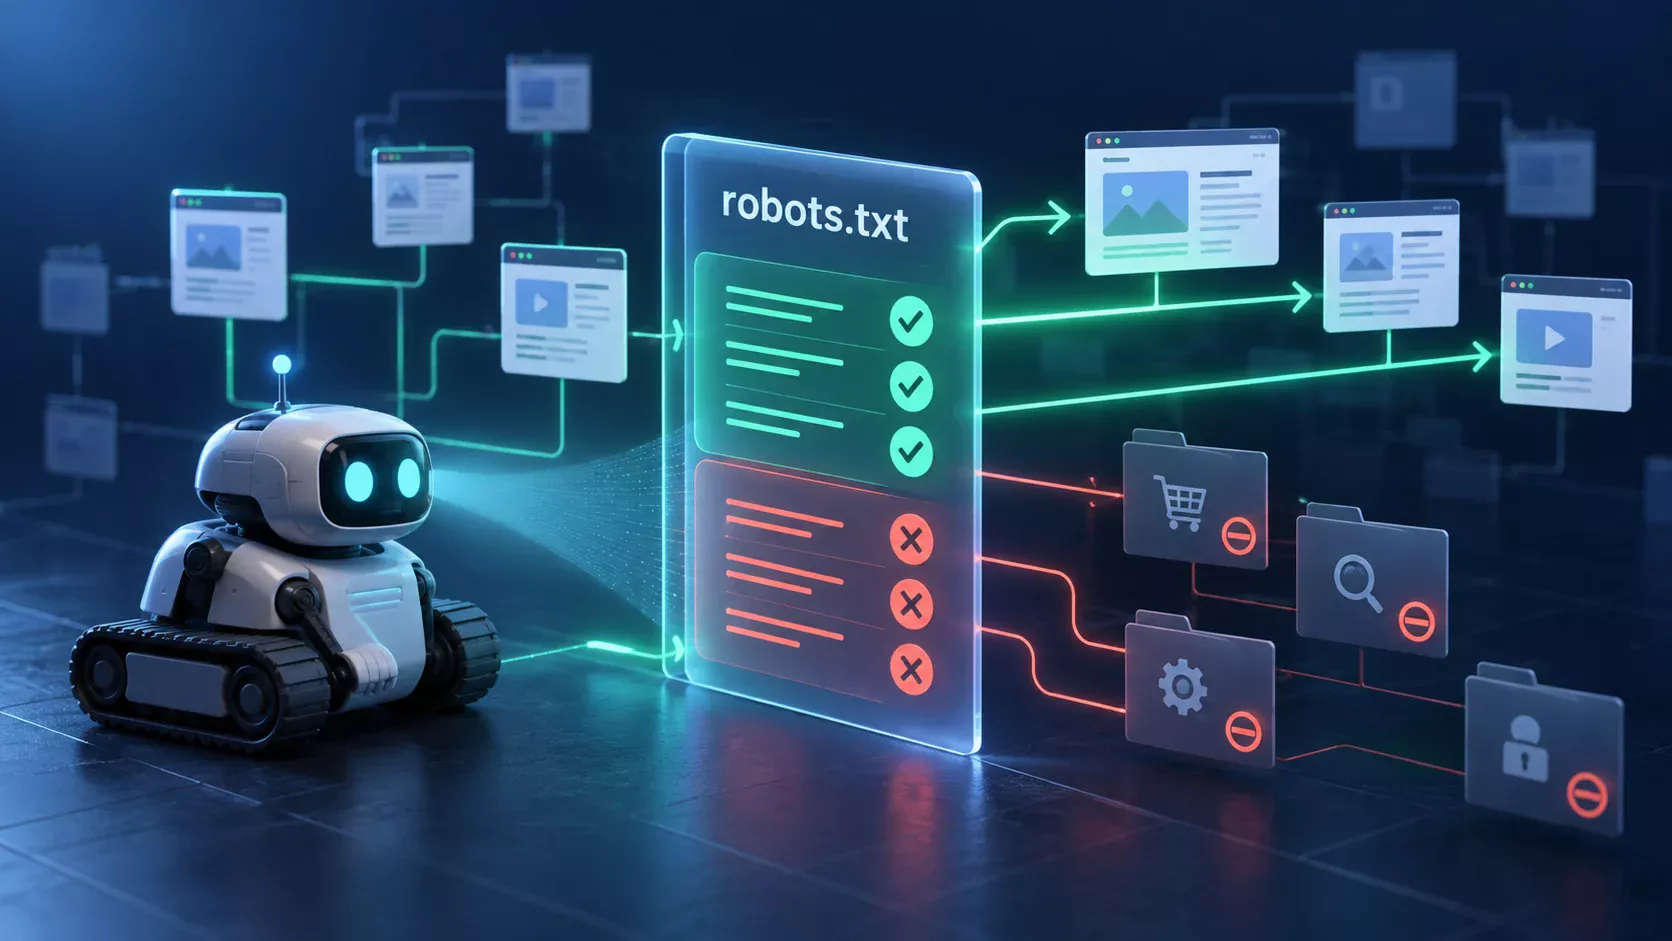
What robots.txt actually does
robots.txt is a plain text file at the root of a website. A compliant crawler requests it before visiting pages and reads the group that matches its user-agent name. Its main purpose is crawl control: allowing useful sections while avoiding URLs that should not be requested repeatedly.
The correct address is https://example.com/robots.txt. Rules apply only to a specific protocol, host and port. A file on www.example.com does not control shop.example.com, and /blog/robots.txt does not replace the root file.
Disallow prevents a crawler from requesting a URL, but it is not a reliable “remove this page from search” command. If a blocked URL is known through internal or external links, a search engine may still display the address without page content.To remove an HTML page from search, keep it crawlable and add noindex in a meta tag or HTTP header. Protect confidential data with authentication. Removed pages should return 404 or 410. Each tool has a different job.
Syntax: five directives you need to understand
| Directive | Meaning | Example |
|---|---|---|
User-agent | Selects the crawler for this rule group. An asterisk means all crawlers. | User-agent: * |
Disallow | Prevents crawling of the specified path. | Disallow: /cart/ |
Allow | Opens a more specific path inside a blocked section. | Allow: /catalog/public/ |
Sitemap | Provides the absolute URL of an XML sitemap. | Sitemap: https://example.com/sitemap.xml |
# | Starts a human-readable comment and is not treated as a rule. | # Cart and checkout |
A minimal safe file
If crawlers may access the entire public website, you do not need a complex configuration. A general group and a sitemap reference are enough:
User-agent: *
Disallow:

Sitemap: https://example.com/sitemap.xml
An empty Disallow means there is no restriction. In contrast, Disallow: / blocks the entire host. Confusing these two versions often destroys organic traffic when a staging configuration is moved to production.
How a matching rule is selected
For one crawler, matching Allow and Disallow rules are compared and the most specific path wins. This lets you open a single folder or file within a blocked directory:
User-agent: *
Disallow: /private/
Allow: /private/public-guide.pdf
Paths can be case-sensitive where /Catalog/ and /catalog/ are different URLs. The * character matches a sequence of characters, while $ anchors the end of a URL. Use patterns only after testing them against real addresses.
# Block PDF URLs, but not HTML pages
User-agent: Googlebot
Disallow: /*.pdf$
Safe templates for different website types
Never copy a template blindly. First list the website’s real URL patterns, define the purpose of every section and decide which pages should appear in search.
A corporate website
User-agent: *
Disallow: /admin/
Disallow: /search/
Disallow: /thank-you/
Disallow: /api/

Sitemap: https://example.com/sitemap.xml
This example blocks the admin area, internal search, a technical thank-you page and an API. Service pages, the blog, images, CSS and JavaScript remain accessible.
WordPress
User-agent: *
Disallow: /wp-admin/
Allow: /wp-admin/admin-ajax.php
Disallow: /?s=
Disallow: /search/

Sitemap: https://example.com/wp-sitemap.xml
For WordPress, it is usually enough to block the admin area, allow admin-ajax.php and limit internal search results. Do not block all of /wp-content/: it contains images, styles and scripts required to render pages correctly.
An ecommerce site with filters
User-agent: *
Disallow: /cart/
Disallow: /checkout/
Disallow: /account/
Disallow: /compare/
Disallow: /wishlist/
Disallow: /*?sort=
Disallow: /*?view=
Disallow: /*?page_size=

Sitemap: https://shop.example.com/sitemap.xml
Carts, checkout, account pages and technical sorting parameters are usually unnecessary in search. Faceted filters require a separate strategy: some combinations may be valuable landing pages that match real demand.
Separate rules for a specific crawler
If one crawler needs special rules, create a dedicated group. Do not assume it automatically inherits the general group: a crawler selects the most specific matching group.
User-agent: Googlebot
Disallow: /temporary-for-google/

User-agent: *
Disallow: /private-for-all/

Sitemap: https://example.com/sitemap.xml
Crawl-delay appears in old examples, but Googlebot does not support it. If a server is overloaded, address performance and endless crawl spaces instead of relying on an unsupported directive.
robots.txt, noindex, canonical and sitemap are different tools
| Tool | Purpose | When to use it |
|---|---|---|
robots.txt | Controls crawling of URLs. | Cart, internal search, endless parameters and service sections. |
noindex | Prevents an accessible page from appearing in search results. | A page is useful to users but should not be indexed. |
canonical | Indicates a preferred version among duplicate URLs. | The same or very similar content is available at multiple addresses. |
sitemap.xml | Lists preferred canonical pages. | Helps discovery and provides structural control. |
| Password or authentication | Actually restricts access to data. | Accounts, internal documents, staging and confidential files. |
The most dangerous combination is blocking a page in robots.txt while adding noindex to it. The crawler cannot open the page to read the indexing instruction. First allow crawling and wait for noindex to be processed; only then decide whether crawl blocking is still necessary.
robots.txt does not solve duplicate content either. If several URLs should consolidate signals into one page, use a correct redirect or canonical URL instead of hiding the problem from crawlers.
Common mistakes that reduce search visibility
| Mistake | What happens | How to fix it |
|---|---|---|
Disallow: / on production | Every page is blocked from crawling. | Remove the global block and recheck the file after deployment. |
| CSS and JavaScript are blocked | The crawler sees a page without its proper design or functionality. | Allow resources needed to render main content. |
| robots.txt is used as security | Secret paths are publicly listed. | Use passwords, authentication and server-side restrictions. |
A noindex page is blocked | The crawler cannot read the tag and remove the URL from search. | Allow crawling until noindex is processed. |
| Rules are copied from another CMS | Useful directories and landing pages are accidentally blocked. | Build rules from your own URL patterns and website logic. |
| Every parameter is blocked | Useful filters or language versions may disappear. | Separate wasteful parameters from valid landing pages. |
| A relative Sitemap path is used | Crawlers may handle the address unpredictably. | Use a full URL including protocol and host. |
| Only the home page is tested | Errors remain in categories and templates. | Test representative URLs of every type. |
How to test robots.txt before publishing
- Open the file in a browser.
/robots.txtshould return200and display plain text, not an HTML template, a login redirect or a server error. - Prepare representative URLs. Include the home page, a service, an article, a category, a product, a filter, internal search, cart, account and a test technical URL.
- Match every URL to a rule. Do not review the file by sight alone; determine which exact rule applies to each address.
- Inspect important pages in Search Console. URL Inspection shows whether Google can access and crawl a page.
- Check the sitemap. An XML sitemap should contain only canonical
200pages that are not blocked and do not usenoindex. - Repeat the test after deployment. CMS plugins, a CDN or hosting environment can modify robots.txt outside the source code.
Disallow: /.A low-risk robots.txt workflow
Start with a URL map, not directives. Split addresses into three groups: pages that should rank, technical URLs needed by users, and wasteful or endless combinations. Choose the right tool for each group.
- Export every URL type from the CMS, sitemap and crawler.
- Mark pages that bring traffic, links or conversions.
- Review parameters, filters, internal search, sorting and date archives.
- Fix status codes, redirects, canonical tags and noindex first.
- Only then limit genuinely unnecessary crawling.
- Save the previous file version and the change date.
- Review Search Console and server logs several days later.
On a small corporate website, robots.txt should normally stay short. A large file with dozens of patterns often signals that the URL structure and CMS need a separate technical SEO audit.
Questions and answers
Does every website need a robots.txt file?
No. If crawlers may access the whole site, the file can be empty or absent. In practice it is often created to provide a clear sitemap reference and document technical sections.
Can robots.txt remove a page from Google?
Not reliably. Disallow limits crawling, but a URL can remain in search if other pages link to it. Use noindex while crawling is allowed, or restrict access with authentication.
Should CSS and JavaScript be blocked?
Usually not. Search engines need styles and scripts to see a page approximately as a user does. Block only resources that do not affect useful content.
Does Google support Crawl-delay?
Googlebot does not use Crawl-delay from robots.txt. Fix server performance and endless crawl spaces instead.
Where must robots.txt be located?
At the host root: https://example.com/robots.txt. Every subdomain and protocol has its own rules.
Sources
This guide is based on the official Google Search Central documentation and the Robots Exclusion Protocol standard: